Tetrion Labs

Mathematical verification for AI‑assisted code.

AI helps write the code. mathema checks what that code actually guarantees, proving it mathematically where it can and gathering executable evidence where it can't. No model is in the loop, and nothing leaves your machine.

Built for
  • technology teams whose productivity gains in writing code aren't translating into better software
  • developers who don't trust vibe coding
  • industries where accountability for decisions is paramount
$ pip install "mathema[all]"
$ mathema audit your_package
# map every function: claimed, provable, tested
$ 
01 · the problem

Code is cheap now, and certainty is not.

AI has made code cheap to produce. Knowing it is correct is still expensive, and as generation speeds up, review becomes the bottleneck. mathema adds a verification layer between AI-assisted code and trusted systems.

[ verification ]

A verification layer for AI-assisted code

mathema turns what a function is meant to do into explicit claims and checks them against the real code, by proof where it can and by evidence where it cannot, so shipping faster stops meaning knowing less. Verification is what turns AI-assisted code into value you can rely on.

[ beyond tests ]

A passing test is not a proof

A test checks the inputs someone chose to write down. It does not establish behaviour beyond them, and generated tests can inherit the biases of the model that wrote the code.

A claim states what should be true. mathema determines whether it is proved, supported by evidence, or falsified, and gives you the counterexample when it fails.

mathema complements your test suite rather than replacing it: existing tests continue to count toward your implementation score.

02 · the gap

Your test passes at one point. mathema proves it everywhere.

Put-call parity says a call minus a put on the same strike equals S - K*exp(-r*T), whatever the volatility. Here it is checked two ways against the same Black-Scholes pricer.

[ the unit test ]

1 point

checked. Every other input is unknown, and hoped for the best.

pytest -q → 1 passed

[ mathema ]

Every point

in range, proved mathematically: every combination of inputs at once, not a sample of them.

mathema check → 1 proven

$ mathema check options.py
ok   options.put_call_parity_gap   1 proven
03 · independent

Zero models in the loop.

For verifying claims: no LLMs no hallucinations no token costs

A second model reviewing the first can share its blind spots. No model is involved in a verdict, so the check stays independent of whatever wrote the code.

Under the hood it is built on symbolic algebra: SymPy for exact proof, an SMT solver (z3) as an optional further decision procedure, and a suite of algorithms that turn code into mathematics and handle the places where an implementation can go wrong, from folding loops and solving for poles to interval evaluation and checks for overflow, numerical stability and how a value is represented.

[ independent ]

Not another model. No LLM is involved in verifying a claim. Verdicts come from proof and from running the real function, so the same evidence stands however the code was written.

[ human in charge ]

Agents propose. They can't adjudicate. Verification happens outside the agent, and accepting a result stays a human decision, kept off every agent and MCP surface.

[ local ]

Runs on your machine. No account, no upload, no API key, no telemetry. Your source never leaves the laptop or the CI runner it lives on.

[ zero tokens ]

Nothing to pay per verification. With no model in the loop, running mathema on every commit costs compute you already have, and every counterexample names the exact inputs, ready to paste into a REPL.

We call this a System 0 engine: zero models between the code and its verdict.

04 · how it works

Accept discoveries, not diffs.

A diff grows with every line AI writes, so reading diffs does not scale. mathema states what each function should do, verifies it, and turns any change in behaviour into a discovery for a person to accept. It implements the open Claim-Driven Development spec, so any tool can read the same records.

  1. 1 · state claims

    What a function should do, written like mathematics: by people, drafted by coding agents, or suggested by mathema.

  2. 2 · verify

    Proved over the whole declared range where possible, tested hard where not, with any counterexample kept.

  3. 3 · accept

    A person accepts each result and each discovery about behaviour. An agent cannot.

  4. 4 · kept in sync

    When the code changes, the evidence and sign-offs it touches go stale, and mathema verify re-checks only what moved.

repeats whenever the code changes

Less to hold in your head. A proof covers every input, so a reviewer no longer has to imagine the cases a test might have missed.

Changes arrive as decisions. Not what was edited, but which claims now hold, fail or have gone stale.

A record of who decided. Who accepted what, when, and against which version of the code.

Every claim carries its status, and its evidence.

proven
Established by mathematical proof over the whole declared range.
d(f(s,k,r,t,sigma), s) >= 0 a call rises with the stock
holds
Supported by sampled evidence that searched for failures, and reported as evidence, never as proof.
f(s,k,r,t,sigma) >= 0 a call is never negative
falsified
A counterexample shows the claim fails: a bug, or a discovery about what the code really does. The record keeps it.
t = -1 put-call parity with no range stated
stale
The code changed since this evidence or sign-off, so it no longer counts until it is re-checked and accepted again.
unclaimed
Nothing has been stated about what this code should do, so nothing is known beyond what ran.

Works with your tests, types, CI and coding agents. More in the docs:

05 · measure

How much of this code do you actually understand?

Tests tell you what ran. mathema measures what has been claimed, verified and pinned down, as three scores reported in your terminal and in CI. Each is measured on its own, so a strength in one can't hide a gap in another.

The overall score is the area the three span, so it falls toward zero when any one of them is empty instead of averaging politely over the gap.

[ mathema ] CLARITY 50% IMPL 100% INTENT 26% 32% overall
mathema badges for the docs example: every line exercised, intent a quarter specified.
[ implementation ]

Coverage that counts proofs

The share of statements reached by a test, a probe or a derive proof, taken together, so code proven symbolically counts even where no test calls it. Coverage reports are stamped by content hash, so lines from a stale report are left out rather than counted.

[ intent ]

What the code is meant to do, stated

How much of what each function is meant to do is explicitly specified and up to date, so intent that lives only in someone's head, or in a prompt that was thrown away, shows up as a gap.

[ clarity ]

Behaviour: how much is pinned down

Of everything knowable about a function, how much its verified claims have settled: what it computes, what it accepts, its bounds and shape, how safely it runs and where it can go wrong. A proof counts for more than a sample, and a failure found is still knowledge.

[ in CI ]

A gate, not a dashboard. mathema verify re-checks only the functions whose structure changed. A falsified claim exits 1 and a broken invocation exits 2, so a pipeline can tell a real finding from a broken run. mathema init --ci scaffolds the GitHub Actions or GitLab step.

[ over time ]

Scores you can diff. mathema badges writes the three scores, the triangle and a per-function snapshot for each commit, so CI can report how the picture moved. The scoring algorithm is versioned, so a change in method never reads as a regression.

06 · quick start

Proven in five minutes.

One function, one claim, and real output from a fresh install. The full walkthrough in the docs starts with a claim that fails, which is rather the point: mathema found the gap by looking, not by being told where to look.

[ 1 · audit ]

Install, then map your code

$ pip install "mathema[all]"
$ mathema audit your_package
[ 2 · declare ]

State a claim where the code lives

def discounted(price: float, rate: float) -> float:
    """The price after applying a discount rate.

    Claims:
        never_raises_price: for price in [0, 1e6], rate in [0, 1], f(price, rate) <= price
    """
    return price * (1 - rate)
[ 3 · check ]

Find out whether it holds

$ mathema check pricing.py
ok   pricing.discounted: source, no side effects; claims 1/1 adjudicated (1 proven, 0 holds, 0 falsified)
07 · design partners

Help shape verification of AI at enterprise scale.

We're working with a small number of engineering teams to shape where mathema goes next. Design partners get the founding engineering team working alongside theirs to verify their first codebase, and a direct say in what we build.

08 · about

Human understanding must keep pace with machine capability.

Tetrion builds the tools that make machine reasoning verifiable and its uncertainty explicit, so that people still make the decisions that matter.

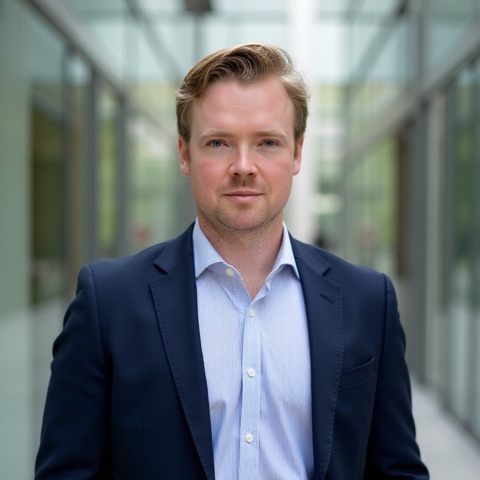
Aaron Byrne

Founded by

Aaron Byrne, PhD

Aaron has spent well over a decade building machine learning models and AI systems for banks around the world, where one mistake can cost millions and every model answers to a regulator. Most recently he was Head of Data Science at a tier-one bank, heavily involved in rolling out AI across the business.

09 · contact

Talk to us.